Cisco ASA Log Processing with ZephFlow
This tutorial demonstrates building a ZephFlow pipeline to parse Cisco ASA firewall logs and transform them into standardized OCSF format for security analytics and storage.
This tutorial demonstrates how to build a data transformation pipeline using ZephFlow to process Cisco ASA firewall logs and convert them into a standardized format. The example code illustrates ZephFlow's powerful capabilities for log parsing, filtering, and transformation.
Introduction
Network security devices like Cisco ASA firewalls generate vast amounts of log data in proprietary formats that can be challenging to analyze. This example demonstrates how to use ZephFlow to:
- Parse Cisco ASA log messages
- Extract structured information from different message types
- Transform the data into a standardized format (OCSF - Open Cybersecurity Schema Framework)
- Output the normalized data for analysis or storage
The example handles multiple Cisco ASA message types (106023, 302013, 305011, etc.), each representing different network records like connection builds, teardowns, access denials, and more.
The whole pipeline is a YAML DAG run with the ZephFlow CLI starter. The complete OCSF mapping expressions for each message type can be generated with the OCSF Mapping App.
Setup
Install the CLI Starter
The pipeline is defined as a YAML DAG and run with the ZephFlow CLI starter. Pull the CLI starter Docker image:
docker pull fleak/zephflow-clistarter:latest
See Running ZephFlow as a Standalone Process with CLI Starter for more details.
Understanding the Example
The example processes Cisco ASA logs through a series of transformation steps. Here's the high-level pipeline structure:
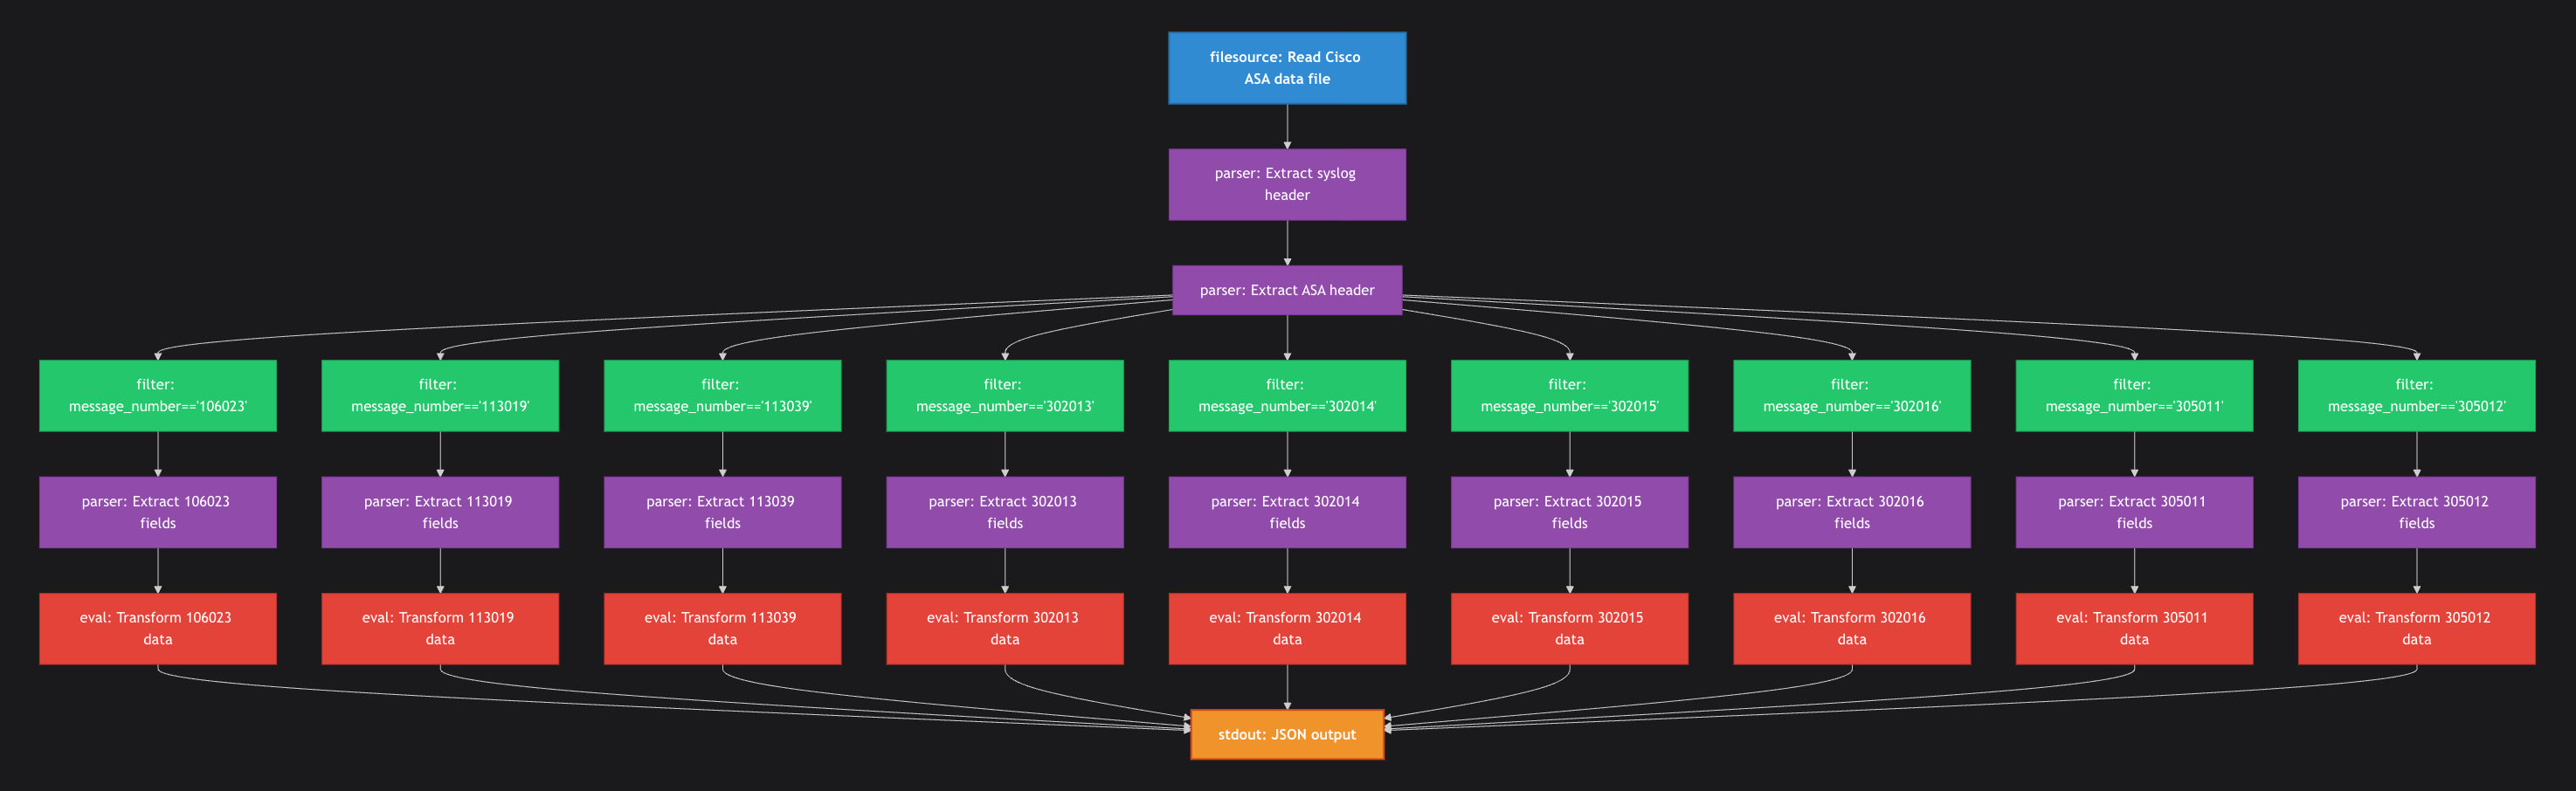 The pipeline follows this flow:
- Read log data from a file source
- Parse the syslog header (timestamp, device ID, etc.)
- Parse the ASA-specific header (message ID, severity, etc.)
- Branch into multiple processing paths based on message type
- For each message type:
- Extract specific fields using Grok patterns
- Transform data into a standardized format
- Output the transformed data as JSON
How the Pipeline Works
Let's examine the key components:
Source Configuration
The pipeline begins by setting up a file source that reads Cisco ASA log data:
- id: "file_source"
  commandName: "filesource"
  config:
    filePath: "/app/asa.log"
    encodingType: "STRING_LINE"
  outputs:
    - "syslog_header_parser"
The STRING_LINE encoding type tells the file source node to treat every text line as a separate record. Every string
record is put into a reserved field called __raw__.
A log message
Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256
will become:
{
  "__raw__": "Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256"
}
Syslog Header Parsing
For more info about the parser node, check the Parser Node Reference.
The first stage parses the syslog header structure:
- id: "syslog_header_parser"
  commandName: "parser"
  config:
    targetField: "__raw__"
    extractionConfig:
      type: "syslog"
      componentList:
        - "TIMESTAMP"
        - "DEVICE"
        - "APP"
      messageBodyDelimiter: ":"
      timestampPattern: "MMM dd yyyy HH:mm:ss"
  outputs:
    - "asa_header_parser"
The above node is a Parser node with Syslog Extraction configuration. This extracts the syslog
headers:
- Timestamp (e.g., "Oct 10 2023 12:34:56")
- Device ID (e.g., "firewall1")
- Application name (e.g., "CiscoASA[123]")
The above example log will become:
{
  "__raw__": "Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "deviceId": "localhost",
  "appName": "CiscoASA[999]",
  "content": "%ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "timestamp": "Oct 10 2018 12:34:56"
}
ASA Header Parsing
The second stage parses the Cisco ASA specific header. This time it's using the Grok extraction configuration:
- id: "asa_header_parser"
  commandName: "parser"
  config:
    targetField: "content"
    removeTargetField: true
    extractionConfig:
      type: "grok"
      grokExpression: "%ASA-%{INT:level}-%{INT:message_number}: %{GREEDYDATA:message_text}"
  outputs:
    - "filter_305011"
    # ... one filter node per message type ...
This extracts:
- Message severity level (e.g., "6")
- Message number (e.g., "302013")
- Message text (the remaining content)
This will transform the log into:
{
  "message_text": "Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "level": "6",
  "appName": "CiscoASA[999]",
  "message_number": "305011",
  "__raw__": "Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "deviceId": "localhost",
  "timestamp": "Oct 10 2018 12:34:56"
}
Message-Type Specific Processing
Up to this point, we have extracted the message type (number) for each log. For each message type, the pipeline branches into dedicated processing paths. Here's an example for message 106023:
- id: "filter_305011"
  commandName: "filter"
  config:
    expression: "$.message_number=='305011'"
  outputs:
    - "parse_305011"

- id: "parse_305011"
  commandName: "parser"
  config:
    targetField: "message_text"
    extractionConfig:
      type: "grok"
      grokExpression: "%{WORD:action} %{WORD:translation_type} %{WORD:protocol} translation from %{WORD:source_interface}:%{IP:source_ip}/%{INT:source_port} to %{WORD:dest_interface}:%{IP:dest_ip}/%{INT:dest_port}"
  outputs:
    - "ocsf_305011"

- id: "ocsf_305011"
  commandName: "eval"
  config:
    expression: |
      dict(...detailed transformation...)
  outputs:
    - "stdout_sink"
Each branch:
- Filters for a specific message type
- Parses the message text with a message-specific Grok pattern and produces a fully parsed log entry:
{
  "level": "6",
  "dest_interface": "outside",
  "appName": "CiscoASA[999]",
  "message_number": "305011",
  "__raw__": "Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "deviceId": "localhost",
  "source_ip": "172.31.98.44",
  "translation_type": "dynamic",
  "message_text": "Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "protocol": "TCP",
  "source_interface": "inside",
  "source_port": "1772",
  "dest_ip": "100.66.98.44",
  "action": "Built",
  "dest_port": "8256",
  "timestamp": "Oct 10 2018 12:34:56"
}
- Transforms the parsed log using the Fleak Eval Expression Language (FEEL) into OCSF format:
{
  "metadata": {
    "log_level": "6",
    "product": {
      "name": "CiscoASA",
      "vendor_name": "Cisco"
    },
    "logged_time": 1539174896000,
    "version": "1.4.0",
    "log_name": "ASA",
    "event_code": "305011"
  },
  "category_uid": 4,
  "status_code": "305011",
  "src_endpoint": {
    "interface_name": "inside",
    "port": "1772",
    "type_id": 1,
    "ip": "172.31.98.44"
  },
  "message": "Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "url": {
    "scheme": "tcp",
    "port": 8256,
    "hostname": "100.66.98.44"
  },
  "status_detail": "Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256",
  "proxy": {
    "interface_name": "outside",
    "type": "Server",
    "port": 8256,
    "type_id": 1,
    "ip": "100.66.98.44"
  },
  "status_id": 1,
  "connection_info": {
    "boundary": "External",
    "boundary_id": 3,
    "protocol_num": 6,
    "direction_id": 2,
    "direction": "Outbound",
    "protocol_name": "tcp"
  },
  "class_uid": 4001,
  "activity_id": 1,
  "time": 1539174896000,
  "severity_id": 1,
  "dst_endpoint": {
    "interface_name": "outside",
    "port": "8256",
    "type_id": 1,
    "ip": "100.66.98.44"
  },
  "type_uid": 4001001,
  "status": "Success"
}
The complex eval expressions in this example were generated using the free Fleak OCSF mapping app, which helps create data transformations to the Open Cybersecurity Schema Framework.
Merging and Output
Finally, all the branches are merged and sent to a stdout sink. In the DAG, branches merge by listing the same node
in their outputs: the last node of every branch points to the sink.
- id: "ocsf_106023"
  commandName: "eval"
  config:
    expression: |
      dict(...detailed transformation...)
  outputs:
    - "stdout_sink"

- id: "ocsf_113019"
  commandName: "eval"
  config:
    expression: |
      dict(...detailed transformation...)
  outputs:
    - "stdout_sink"

# ... other branches, each ending with outputs: ["stdout_sink"] ...

- id: "stdout_sink"
  commandName: "stdout"
  config:
    encodingType: "JSON_OBJECT"
  outputs: []
Running the Pipeline
Putting it together, the DAG below runs the pipeline end to end for message type 305011. Its eval node is a shortened
version of the OCSF mapping that fills in a subset of the fields shown above; the complete expressions for every message
type can be generated with the OCSF Mapping App. Save it as asa_to_ocsf.yml:
jobContext:
  otherProperties: { }
  metricTags:
    env: "default_env"
    service: "default_service"
  dlqConfig: null

dag:
  - id: "file_source"
    commandName: "filesource"
    config:
      filePath: "/app/asa.log"
      encodingType: "STRING_LINE"
    outputs:
      - "syslog_header_parser"

  - id: "syslog_header_parser"
    commandName: "parser"
    config:
      targetField: "__raw__"
      extractionConfig:
        type: "syslog"
        componentList:
          - "TIMESTAMP"
          - "DEVICE"
          - "APP"
        messageBodyDelimiter: ":"
        timestampPattern: "MMM dd yyyy HH:mm:ss"
    outputs:
      - "asa_header_parser"

  - id: "asa_header_parser"
    commandName: "parser"
    config:
      targetField: "content"
      removeTargetField: true
      extractionConfig:
        type: "grok"
        grokExpression: "%ASA-%{INT:level}-%{INT:message_number}: %{GREEDYDATA:message_text}"
    outputs:
      - "filter_305011"

  - id: "filter_305011"
    commandName: "filter"
    config:
      expression: "$.message_number=='305011'"
    outputs:
      - "parse_305011"

  - id: "parse_305011"
    commandName: "parser"
    config:
      targetField: "message_text"
      extractionConfig:
        type: "grok"
        grokExpression: "%{WORD:action} %{WORD:translation_type} %{WORD:protocol} translation from %{WORD:source_interface}:%{IP:source_ip}/%{INT:source_port} to %{WORD:dest_interface}:%{IP:dest_ip}/%{INT:dest_port}"
    outputs:
      - "ocsf_305011"

  - id: "ocsf_305011"
    commandName: "eval"
    config:
      expression: |
        dict(
          class_uid=4001,
          category_uid=4,
          activity_id=1,
          type_uid=4001001,
          time=ts_str_to_epoch($.timestamp, "MMM dd yyyy HH:mm:ss"),
          message=$.message_text,
          metadata=dict(
            version="1.4.0",
            log_name="ASA",
            log_level=$.level,
            event_code=$.message_number,
            product=dict(name="CiscoASA", vendor_name="Cisco")
          ),
          src_endpoint=dict(interface_name=$.source_interface, ip=$.source_ip, port=$.source_port),
          dst_endpoint=dict(interface_name=$.dest_interface, ip=$.dest_ip, port=$.dest_port),
          connection_info=dict(protocol_name=lower($.protocol))
        )
    outputs:
      - "stdout_sink"

  - id: "stdout_sink"
    commandName: "stdout"
    config:
      encodingType: "JSON_OBJECT"
    outputs: [ ]
Create a log file with the sample message:
echo 'Oct 10 2018 12:34:56 localhost CiscoASA[999]: %ASA-6-305011: Built dynamic TCP translation from inside:172.31.98.44/1772 to outside:100.66.98.44/8256' > asa.log
Then run the CLI starter, mounting both the DAG definition and the log file:
docker run -i \
  -v $(pwd)/asa_to_ocsf.yml:/app/asa_to_ocsf.yml \
  -v $(pwd)/asa.log:/app/asa.log \
  fleak/zephflow-clistarter:latest -f /app/asa_to_ocsf.yml
The OCSF records are printed to standard output as JSON objects.
Change the Source and Destination
ZephFlow supports interacting with other data source/destination systems. For example, you can read from a source Kafka
topic and write to a destination topic. Replace the file_source node with a Kafka source node, and the stdout_sink
node with a Kafka sink node (the last node of every branch then lists kafka_sink in its outputs):
# Read from Kafka
- id: "kafka_source"
  commandName: "kafkasource"
  config:
    broker: "broker-address:9092"     # Kafka broker address
    topic: "topic-name"               # Topic to consume from
    groupId: "consumer-group-id"      # Consumer group ID
    encodingType: "STRING_LINE"       # Raw log lines; the syslog parser reads __raw__
  outputs:
    - "syslog_header_parser"

# Output to Kafka
- id: "kafka_sink"
  commandName: "kafkasink"
  config:
    broker: "broker-address:9092"     # Kafka broker address
    topic: "output-topic"             # Topic to publish to
    encodingType: "JSON_OBJECT"       # Encoding type for messages
  outputs: [ ]
Conclusion
This example demonstrates ZephFlow's powerful capabilities for log processing pipelines. By combining filtering, parsing, and transformation operations in a flexible DAG structure, you can build sophisticated data processing workflows.
The modular nature of ZephFlow allows you to:
- Process multiple message types with specialized handling
- Extract structured data from unstructured logs
- Transform data into standardized formats
- Output the results to various destinations
For more information on ZephFlow and its capabilities, refer to the ZephFlow documentation.